Does DeepSeek's 75% Less HBM Use Threaten SK Hynix? The Market Missed a Different Number
V4.1 Flash really did cut the HBM used by KV cache to a quarter of its prior level. But reading that as "75% of all AI HBM demand disappears" misreads both the technology and the investment case. What matters now is not the memory savings rate, but how much more AI usage that savings can unlock.
Stocks moved first. The cause was not just one thing
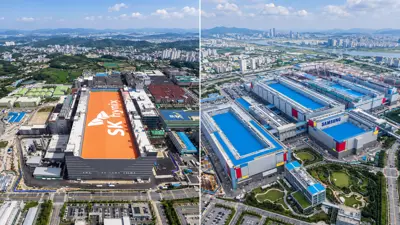
On September 11, Samsung Electronics fell 3.53% and SK Hynix dropped 2.21%. DeepSeek's V4.1 Flash announcement did stir worries that AI models could run on far less memory than assumed.
But pinning the whole selloff on DeepSeek alone is too simple. The KOSPI fell 1.76% that same day. Rising Middle East oil prices and a spike in US Treasury yields were pressing on tech stocks broadly. DeepSeek looks more like an extra headwind that landed on memory stocks in an already weak market.
What DeepSeek actually cut by 75%
The key piece is the KV cache. When a large language model reads a long passage and then generates the next word, it does not recompute everything it already read from scratch. Instead it stores the intermediate information it needs in GPU memory, and that stored information is the KV cache.
Think of it like sticking Post-it notes on important pages of a book. More notes make it faster to find things again, but they take up more space. DeepSeek redesigned this so the notes are much smaller and get reused across multiple layers of the model.
| Metric | What it measures |
|---|---|
| 1/4 | HBM capacity needed for global KV cache, versus the previous V4 Flash |
| 1/8 | SSD storage needed for long-term cache retention |
| 8B / 16B | Of a 552B-parameter model, only 8B activate for input processing and 16B for output generation |
By DeepSeek's own account, V4.1 Flash is a 552-billion-parameter mixture-of-experts (MoE) model, but it activates only 8 billion parameters for input processing and 16 billion for output generation. Compared with the prior generation, it cuts the HBM needed for KV cache to a quarter and the SSD needed for cache storage to an eighth.
The most common misreading
| Announced figure | What it actually means | The exaggerated reading |
|---|---|---|
| HBM cut to 1/4 | KV cache's HBM footprint drops, all else equal | Total HBM in an AI server drops 75% |
| SSD cut to 1/8 | Persistent KV cache storage drops | Total datacenter SSD demand drops 87.5% |
| 8B / 16B active | Expert parameters engaged per token processed | The 552B model is effectively an 8B or 16B model |
MoE "active parameters" are especially easy to misread. Opening only a few shelves you need in a huge library does not make the rest of the books disappear. Even if fewer parameters participate in a given computation, the full model weights still have to be stored and distributed across GPUs.
Training memory is a separate matter entirely. Gradients, optimizer states and intermediate activations draw on a different kind of memory than KV cache does. So this announcement is a major gain in inference efficiency, not an event that cuts total AI memory demand to a quarter.
For server operators, it looks more like "do four times more with the same HBM"
The practical effect of this technology has less to do with removing HBM and more to do with doing more work on the same GPU. Longer conversations can stay live, more users can be served at once, and more coding agents can run in parallel.
This is the point that matters most for HBM investing. Future demand will not be decided simply by how many gigabytes one model uses. Memory per token, concurrent sessions, average context length, and total call volume all move together.
When AI costs fall, companies typically do not bank the savings as cash. They spend it on more inference. A service that once called a model once per search might start calling it dozens of times inside an agent. Efficiency gains can trigger a rebound effect where total usage rises to offset them.
Not exactly reassuring for memory makers either
The risk runs the other way too. If DeepSeek's approach spreads quickly to other frontier and open-source models, and AI usage growth slows at the same time, the picture changes. Servers where KV cache was the bottleneck, especially for long-context and agentic services, could handle the same traffic with fewer GPUs and less HBM.
Part of the demand the memory industry has been counting on assumes that HBM per server keeps rising as models grow larger and contexts grow longer. V4.1 Flash shows that assumption does not hold automatically, at least in this case.
Still, just a day earlier, on September 10, reports emerged that Chinese AI accelerator makers were raising prices 20% to 50% because of HBM shortages. Evidence that HBM remains a bottleneck in actual supply chains exists at the very same time. Efficiency breakthroughs and physical scarcity appear to be coexisting right now.
Insight Times Editorial Desk