Figure's Robot Just Cleaned 30 Homes It Had Never Seen Before
Figure's new Helix 2.5 model made beds and folded towels in 30 unfamiliar Bay Area homes. What matters most may not be the robot's hands, but how well human-behavior pretraining transfers to new places.
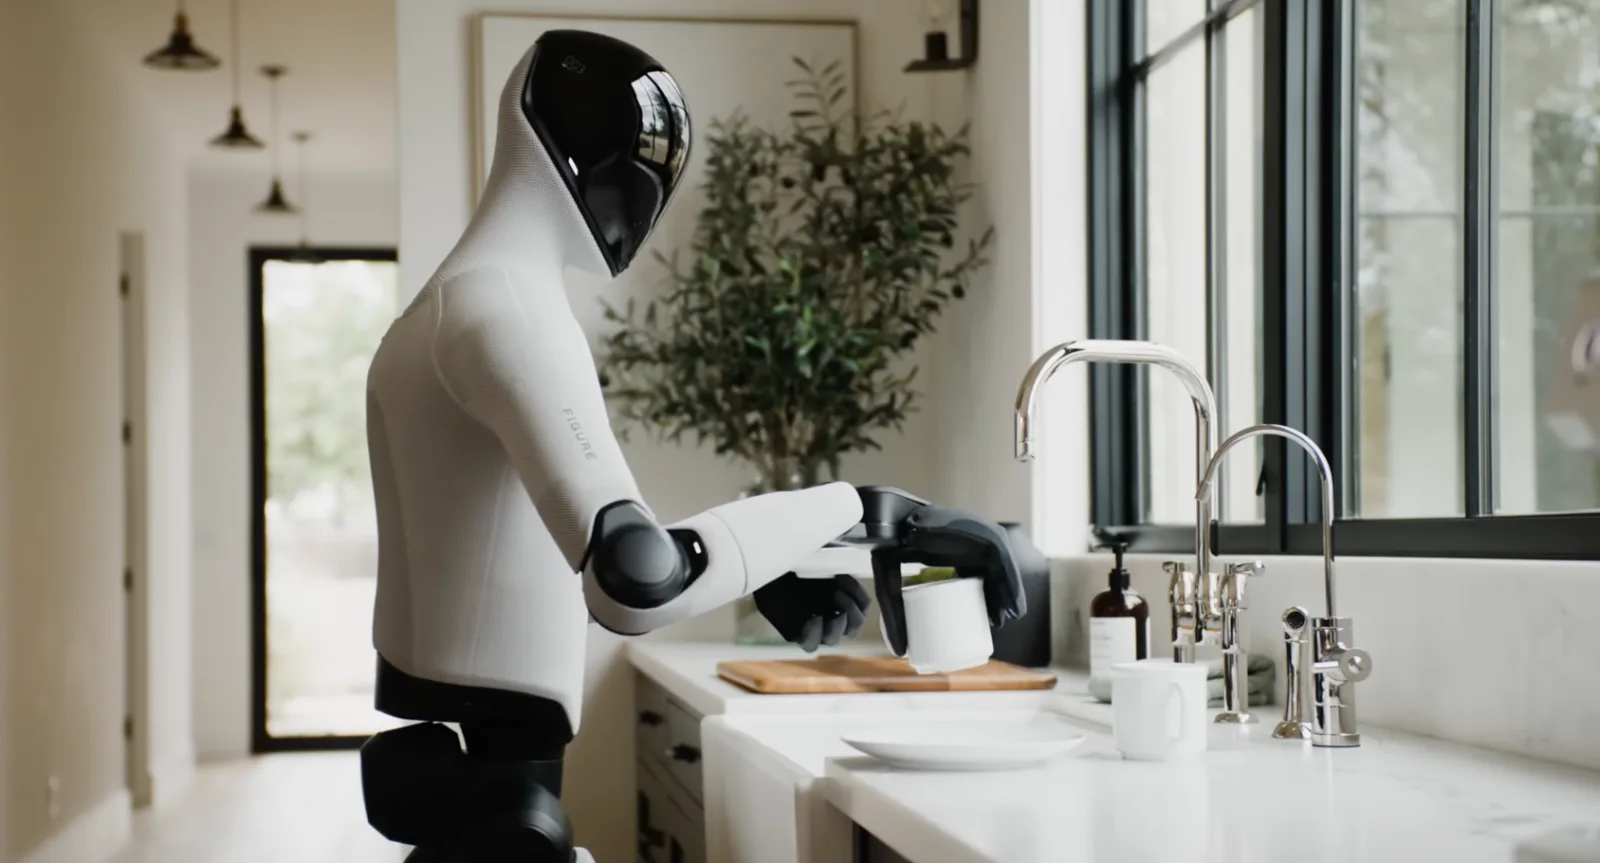
For humans, doing housework in an unfamiliar place is not something you relearn from scratch. Walk into a house you have never entered before, and you still know how to spot the bed, smooth the blanket, and pick things up off the floor. Until now, that basic competence has been one of the hardest problems in robotics.
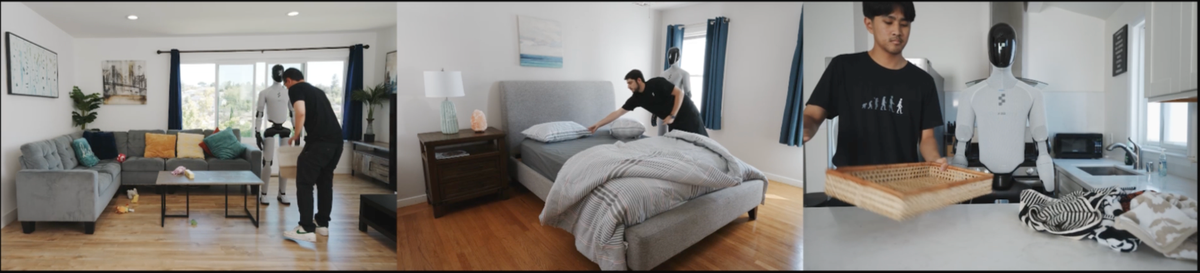
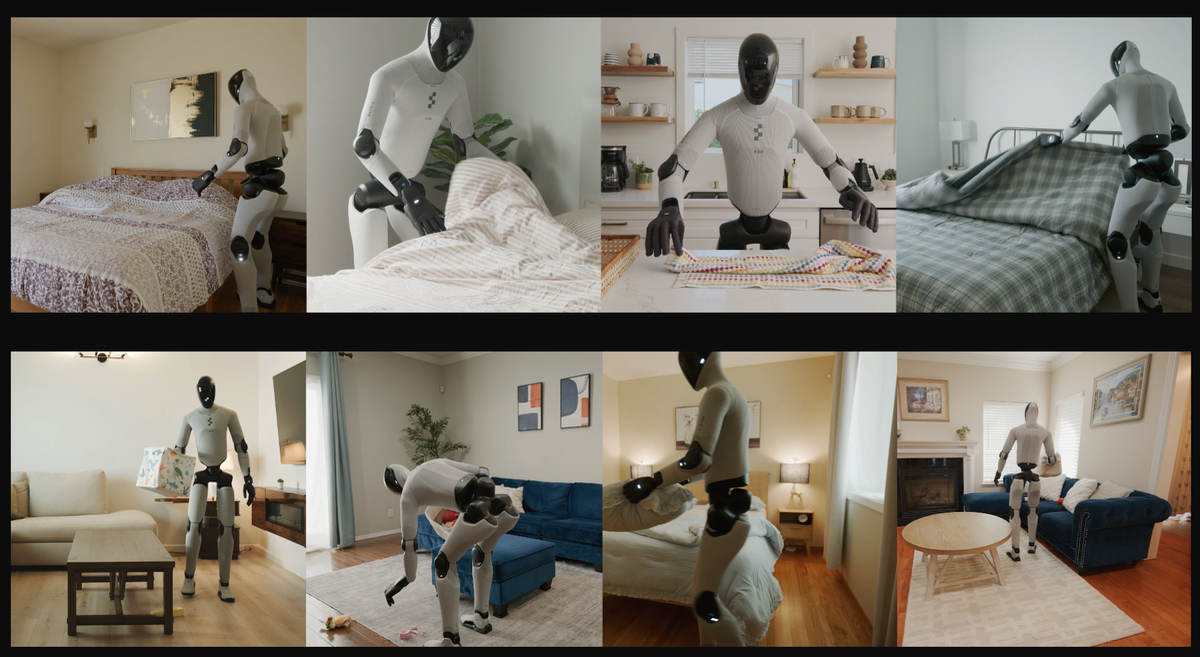
That is exactly where Figure's newly unveiled Helix 2.5 model matters. Figure sent the model into 30 homes it had never encountered before, scattered across the San Francisco Bay Area, and had it tidy living rooms, fold towels, and make beds. There was no prior data collection or environment-specific fine-tuning in the test homes. Figure reported an overall task success rate of 56%.
The word "zero-shot" needs to be read carefully
The word most likely to get overhyped in this announcement is "zero-shot." It does not mean Helix 2.5 suddenly learned to fold towels or make beds with no training at all.
Figure trained the robot on task-specific data for all three chores, collected in other locations. What was zero-shot was the evaluation site and its objects. The robot never saw the layout, toys, towels, or bedding of the 30 test homes during training, and it received no additional adaptation once it arrived on site.
That distinction matters. Many robotic systems today still need to collect and adjust data at the actual deployment site. That approach can work in a single factory, but it does not scale to millions of homes. If every household requires retraining, the economics of a general-purpose home robot simply do not work.
9% to 56%: the number that matters most in this announcement
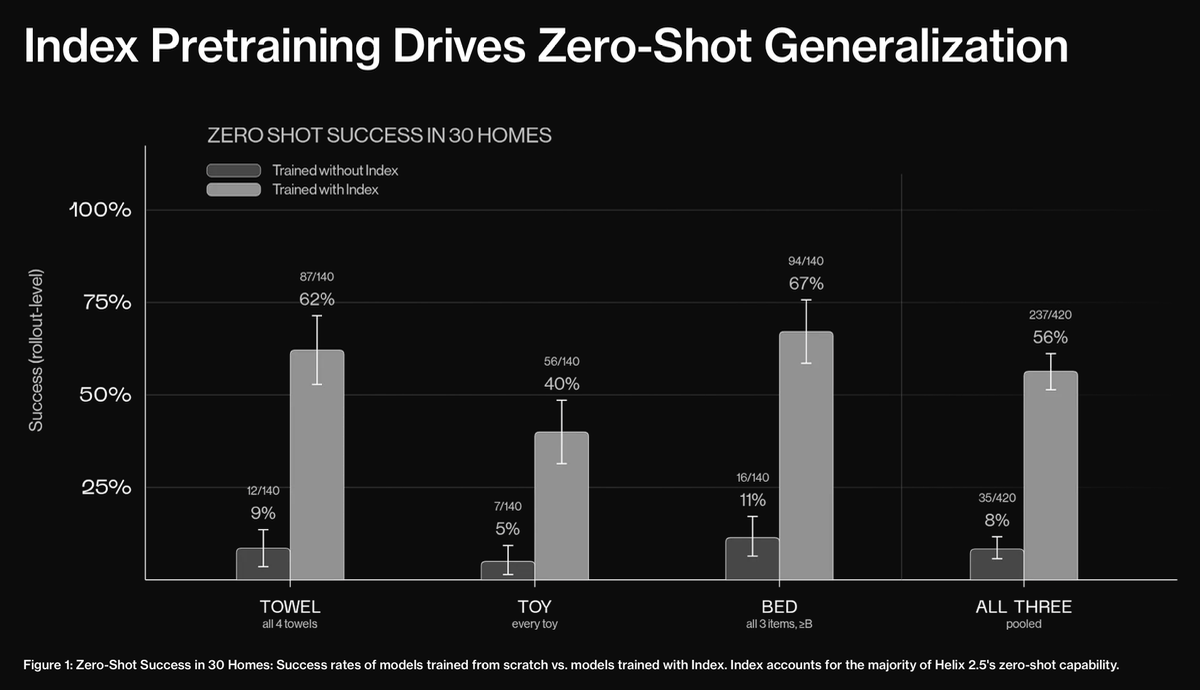
9% — Zero-shot success rate for a policy trained from scratch, without Index pretraining
56% — Overall task success rate for a policy pretrained with Index
30 — Number of real homes evaluated with no prior data collection
Figure isolated the effect of Index pretraining by holding the model architecture, task-specific data, training method, and evaluation conditions constant, and changing only the starting point.
A model trained from scratch scored 9%. A model first pretrained with Index scored 56%. The success bar was not loose, either. Tidying a living room required putting all 13 to 15 toys into a basket. Towels had to be folded and placed in a basket. Beds had to meet a fixed set of criteria all the way through. Partial credit did not count as success.
If the result holds, it could shift the center of gravity in humanoid competition. Better hands or stronger motors alone are not enough. How much diverse human behavior a company can collect, and how broadly it can train that into a single physical world model, may become the core asset.
Is what happened with LLMs starting to happen with robots too
Figure's bigger claim is a scaling law. The company says it trained four models by scaling Index pretraining data across an 8x range, and that the loss in predicting subsequent robot behavior decreased smoothly as data grew. Figure says it predicted the loss of its largest training run to four decimal places using only results from smaller experiments, with a prediction error of just 0.54% of the total range.
This is arguably the biggest industrial implication of the announcement. Language models justified enormous investment on the back of an empirical scaling law: more data and more compute produce predictable performance gains. If a similar relationship holds for robots, developing humanoids could shift from something closer to hands-on engineering tuning toward a data-center-scale training race.
Figure says Index is currently generating roughly 35 minutes of new human-experience data every second. Scaled to a full day, that works out to roughly 5.75 years' worth of footage. The company is also pursuing a deployment of up to 100,000 Nvidia Vera Rubin GPUs with Nscale to train Helix, and has committed an initial $3.5 billion in compute spending.
The picture in one chart
How robots have scaled until now: New location → collect on-site data → retrain → test → deploy
What Helix 2.5 is aiming for: Broad human-behavior pretraining → define the task once → deploy directly to an unseen location
If this architecture actually works, it changes the economics of robot software substantially. It moves the model away from a structure where training costs repeat every time a new customer is added, toward one where the cost of a single foundation model is spread across a huge number of robots and locations.
Still too early to call this the "ChatGPT moment" for home robots
A 56% success rate matters a great deal at the research stage, but a consumer product faces an entirely different bar. It is hard to trust a robot that could fail more than one time in three with tasks like putting away glassware or handling hot cookware.
This evaluation was also designed and run by Figure itself. The diversity of 30 homes is broader than past tests, but three tasks are not enough to prove general physical intelligence. Key commercialization metrics, such as per-task success rates, average completion time, how often a human had to step in for safety, and whether remote assistance was used, are not sufficiently confirmed by this announcement alone.
Reading these results as "the humanoid problem is solved" would be an overstatement. The more accurate reading is that the path from robots that must be retaught in every new environment to robots that transfer knowledge from large-scale pretraining on human experience has, for the first time, produced a fairly concrete set of numbers.
Insight Times Editorial Desk